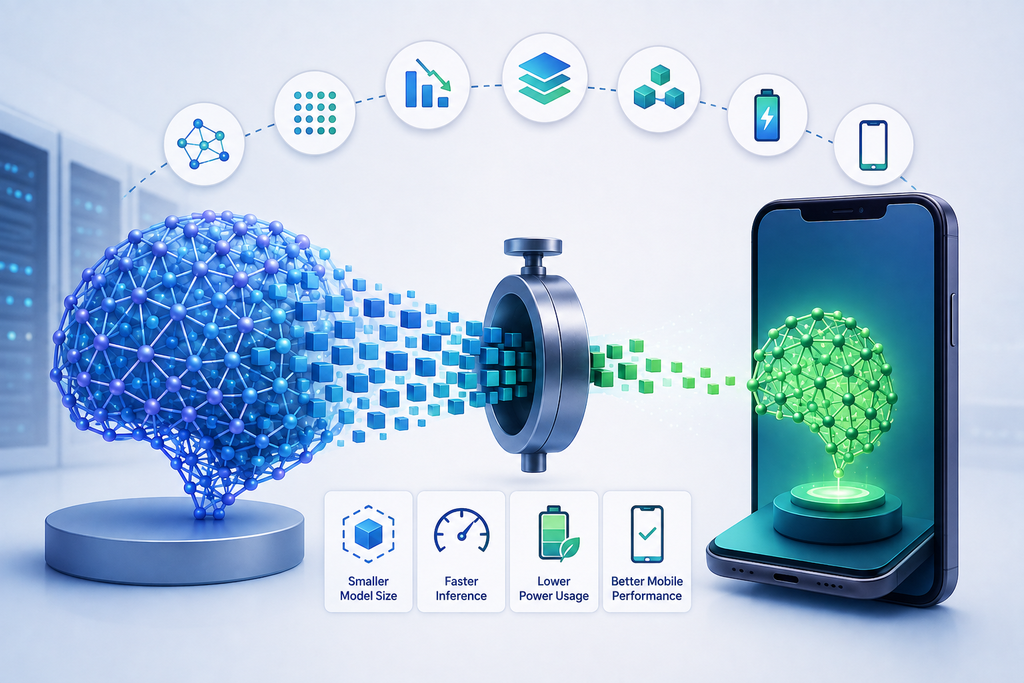
A few months ago, I asked an AI assistant on my phone to summarize a long email while I was standing in line at a coffee shop with terrible signal. No internet, no cloud server, no delay. It just worked, instantly, right there on the device in my pocket. That moment stuck with me, because the same kind of model that powers a chatbot on a data-center server the size of a warehouse was somehow squeezed down small enough to run offline on a phone with a battery that also needs to last all day. The trick behind that, more often than not, is model quantization.
If you’ve ever wondered how something as massive as a large language model, originally built with billions of parameters and running on racks of expensive GPUs, ends up working on a mid-range smartphone, this article is going to pull back the curtain. We’re going to walk through exactly what model quantization is, why it matters so much for efficient LLM deployment, and how engineers make these enormous models small enough to fit in your pocket without completely breaking them in the process.
Table of Contents
- The Problem Quantization Was Built to Solve
- What Model Quantization Actually Means
- A Simple Way to Think About Numbers and Precision
- The Main Types of Model Quantization
- Post-Training Quantization vs Quantization-Aware Training
- Why Efficient LLM Deployment Depends on This Technique
- Popular Tools and Formats Engineers Actually Use
- Real-World Examples of Quantized Models in Action
- The Trade-Offs Nobody Should Ignore
- A Mini Case Study: Shrinking a Model Step by Step
- Common Myths and Misunderstandings
- Where This Technology Is Headed
- FAQ
- Final Thoughts
The Problem Quantization Was Built to Solve
To understand why model quantization exists, you first need to understand the problem it solves. Modern large language models are enormous. A model like Llama or GPT-style architecture can contain anywhere from a few billion to hundreds of billions of individual parameters, and each one of those parameters is a number that needs to be stored and processed.
Traditionally, these numbers are stored using a format called 32-bit floating point, often shortened to FP32. Each parameter in that format takes up four bytes of memory. Multiply that by billions of parameters, and you end up with models that require dozens or even hundreds of gigabytes of memory just to load, before you’ve asked a single question.
A smartphone doesn’t have that kind of room to spare. Most phones ship with somewhere between four and twelve gigabytes of total RAM, and that memory has to be shared across the operating system, your apps, your camera, your messages, everything. There’s simply no realistic way to load a full-precision, multi-billion-parameter model onto a phone and expect it to run smoothly, or at all.
This is exactly the gap that model quantization fills. Instead of asking, “how do we build a smaller model from scratch,” engineers asked a different question: “how do we take an existing, powerful model and represent its numbers more efficiently, without losing too much of what makes it smart?” That question is the entire foundation of efficient LLM deployment on constrained hardware like phones, laptops, and embedded devices.
What Model Quantization Actually Means
At its core, model quantization is the process of reducing the precision of the numbers used to represent a model’s parameters, while trying to preserve as much of the model’s original behavior and accuracy as possible.
Think of it like compressing a high-resolution photograph. A massive, uncompressed image file captures every tiny detail with perfect precision, but it takes up a lot of storage space. Compress it intelligently, and you can shrink the file dramatically while the photo still looks nearly identical to the human eye. You lose some information, technically, but not the information that actually mattered for how the image looks.
Model quantization works on a similar principle, except instead of pixels, it’s compressing the millions or billions of numerical weights inside a neural network. Instead of storing each weight as a precise 32-bit floating point number, quantization converts those weights into a lower-precision format, like 16-bit, 8-bit, or even 4-bit representations.
The result is a model that takes up dramatically less memory and often runs significantly faster, because smaller numbers are cheaper and quicker for a processor to work with. This is the entire reason efficient LLM deployment on phones has become possible at all in the past few years.
A Simple Way to Think About Numbers and Precision
Let’s slow down for a second, because the concept of “precision” can feel abstract if you’re not used to thinking about how computers store numbers.
Imagine you’re measuring the temperature outside. You could say it’s “21.847362 degrees,” which is extremely precise, or you could round it to “22 degrees,” which is far simpler but still practically useful for almost everything you’d want to do with that information, like deciding whether to bring a jacket.
That’s roughly the idea behind model quantization. A weight in a neural network might originally be stored as something like 0.0847362951, with a huge amount of decimal precision. After quantization, that same value might be represented in a much simpler, lower-precision format, something closer to a rounded approximation that uses far fewer bits to store.
Individually, that rounding seems like it shouldn’t matter much. But a model has billions of these numbers working together, and the real engineering challenge in model quantization is making sure that all those tiny roundings, added up across the entire network, don’t meaningfully change how the model behaves. Done carelessly, quantization can make a model noticeably worse. Done well, the difference is often barely noticeable to an actual user.
The Main Types of Model Quantization
Not all model quantization approaches are the same, and understanding the different types helps explain why some quantized models perform better than others.
8-bit Quantization (INT8)
This is one of the more conservative and widely used approaches. Instead of the original 32-bit floating point numbers, weights are converted to 8-bit integers. This alone can shrink a model’s memory footprint to roughly a quarter of its original size, while typically preserving most of the model’s accuracy.
4-bit Quantization (INT4)
This is a much more aggressive form of model quantization, shrinking numbers down even further. It offers dramatic memory savings, sometimes reducing a model’s footprint by nearly eighty-five to ninety percent compared to the original full-precision version. The trade-off is that 4-bit quantization requires much more careful engineering to avoid noticeably degrading the model’s output quality.
Mixed-Precision Quantization
Rather than applying the same level of precision reduction across the entire model, mixed-precision approaches selectively keep certain sensitive parts of the model at higher precision while aggressively quantizing less sensitive parts. This is often used in modern efficient LLM deployment pipelines because it balances size reduction with preserved accuracy more intelligently than a one-size-fits-all approach.
Weight-Only vs Weight-and-Activation Quantization
Some approaches only quantize the model’s stored weights, while leaving the intermediate calculations, called activations, in higher precision during actual use. Others quantize both weights and activations for even greater speed and memory benefits, though this generally requires more sophisticated calibration to avoid errors compounding during inference.
Each of these approaches to model quantization involves genuine trade-offs, and choosing the right one depends heavily on the specific hardware target and how much accuracy loss is acceptable for the use case.
Post-Training Quantization vs Quantization-Aware Training
There are two broad philosophies for how model quantization actually gets applied, and the difference between them matters a lot for the end result.
Post-Training Quantization (PTQ)
This is the simpler and faster approach. Engineers take an already fully trained model and apply quantization to it afterward, without retraining the entire network from scratch. It’s quick, requires far less computing power, and works well for many use cases. The downside is that because the model was never trained with quantization in mind, some accuracy loss is often unavoidable, especially at more aggressive compression levels like 4-bit.
Quantization-Aware Training (QAT)
This approach is more involved. Instead of quantizing after training is complete, the model is trained, or fine-tuned, while simulating the effects of quantization during the training process itself. This allows the model to essentially learn to compensate for the precision loss as it trains, resulting in a final quantized model that typically retains noticeably better accuracy compared to post-training quantization at the same bit level.
The trade-off, unsurprisingly, is cost. Quantization-aware training requires significantly more computational resources and time, since it essentially involves additional training cycles. For many practical applications, especially smaller models intended for efficient LLM deployment on consumer devices, post-training quantization strikes a reasonable balance between simplicity and performance. For larger, more sensitive applications, teams increasingly lean toward quantization-aware training methods to preserve quality at aggressive compression levels.
Why Efficient LLM Deployment Depends on This Technique
It’s worth pausing to really connect the dots here, because model quantization isn’t just an academic technique. It’s the backbone of an entire shift happening in how AI actually reaches everyday users.
A few years ago, running any meaningful language model meant sending a request to a remote server, waiting for a response, and depending entirely on an internet connection. That worked, but it came with real costs: latency, privacy concerns since your data traveled to someone else’s server, and ongoing infrastructure expenses for the companies running those servers.
Efficient LLM deployment directly on personal devices changes that equation entirely. When a model is small enough to run locally, thanks to model quantization, you get near-instant responses because there’s no network round trip. You get better privacy because your data can stay entirely on your device. And companies save enormous amounts of money because they’re not paying for cloud compute for every single user interaction.
This is why nearly every major technology company working on consumer AI, from smartphone manufacturers to laptop chipmakers, has invested heavily in model quantization research. It’s not an optional optimization anymore. It’s the difference between an AI feature that lives exclusively in the cloud and one that can genuinely run anywhere, anytime, even without an internet connection.
Popular Tools and Formats Engineers Actually Use
If you’ve spent any time in AI communities, you’ve probably seen file extensions and tool names thrown around without much explanation. Here’s a practical breakdown of what engineers actually use to apply model quantization in the real world.
GGUF and llama.cpp
GGUF is a file format specifically designed for storing quantized language models efficiently, and it’s closely associated with the llama.cpp project, which allows large language models to run on regular consumer hardware, including laptops and even some smartphones. This ecosystem popularized accessible model quantization for hobbyists and developers who don’t have access to massive data-center infrastructure.
GPTQ and AWQ
These are two popular algorithmic approaches specifically designed for quantizing large language models while minimizing accuracy loss. GPTQ focuses on carefully calibrating quantization layer by layer, while AWQ, short for Activation-aware Weight Quantization, focuses on identifying which weights matter most based on how activations behave, then protecting those weights from aggressive compression. Both approaches represent more sophisticated evolutions of basic model quantization techniques.
BitsAndBytes
This library, widely used within the Hugging Face ecosystem, provides accessible tools for applying 8-bit and 4-bit quantization to models, making it much easier for developers without deep specialization in efficient LLM deployment to still shrink and run large models on more modest hardware.
ONNX Runtime and TensorRT
These are broader frameworks that support model quantization as part of a larger toolkit for optimizing and deploying machine learning models across different hardware platforms, from mobile chips to specialized AI accelerators.
Apple Core ML and Google AI Edge
Both major mobile ecosystems now offer their own frameworks specifically built for efficient LLM deployment directly on their devices, incorporating model quantization as a core part of preparing models to run smoothly on phone-specific chips designed for AI workloads.
Real-World Examples of Quantized Models in Action
This isn’t just theoretical. Model quantization is already running quietly in the background of products people in the US and UK use every single day.
Apple’s on-device intelligence features, which power things like text summarization, notification prioritization, and writing assistance directly on iPhones, rely heavily on quantized models specifically optimized to run efficiently on their custom silicon chips.
Google’s Gemini Nano, designed to run directly on Android devices, is another clear example of efficient LLM deployment made possible through aggressive model quantization, allowing features like on-device summarization and smart replies to function without needing a constant internet connection.
Even outside of big tech products, independent developers regularly take open-source models and apply model quantization themselves using tools like llama.cpp, allowing surprisingly capable AI chatbots to run entirely offline on laptops that don’t have specialized AI hardware at all.
The Trade-Offs Nobody Should Ignore
It would be misleading to present model quantization as some kind of free lunch. Like most engineering decisions, it involves real trade-offs that matter depending on the use case.
Accuracy loss is real, even if often small. Aggressive quantization, particularly at 4-bit or lower, can measurably reduce a model’s performance on complex reasoning tasks, even if casual conversational use feels largely unaffected.
Not all tasks degrade equally. Simple tasks like basic text completion or straightforward summarization tend to hold up well under model quantization. More complex tasks involving nuanced reasoning, math, or long-context understanding tend to be more sensitive to precision loss.
Hardware compatibility varies. Not every chip is optimized to take full advantage of every quantization format. A model quantized for one type of hardware accelerator might not run efficiently on a different one, which is why efficient LLM deployment often requires format-specific and even device-specific optimization work.
Quantization isn’t a substitute for a good base model. No amount of clever model quantization can fix a fundamentally weak or poorly trained model. It optimizes what’s already there; it doesn’t add new capability.
Understanding these trade-offs is what separates a naive approach to shrinking models from genuinely thoughtful efficient LLM deployment engineering.
A Mini Case Study: Shrinking a Model Step by Step
Let’s walk through a simplified, realistic example of how this process might actually unfold for an engineering team preparing a model for a mobile app.
Step one: Start with the full-precision model. The team begins with a model trained at standard 32-bit floating point precision, resulting in a file size of roughly twenty-eight gigabytes. This is far too large for any mobile deployment.
Step two: Apply initial 8-bit model quantization. After converting the model to 8-bit precision, the file size drops to roughly seven gigabytes, a substantial reduction, though still too large for comfortable use on most phones alongside other apps and system processes.
Step three: Test accuracy benchmarks. The team runs the quantized model through a battery of standard evaluation tests, comparing its outputs against the original full-precision version, checking for meaningful drops in quality across different types of tasks.
Step four: Push to 4-bit quantization using AWQ. To hit their target size for smooth mobile performance, the team applies a more aggressive 4-bit quantization technique that specifically protects the most sensitive weights, bringing the file size down to roughly three and a half gigabytes.
Step five: Fine-tune and re-test. Recognizing some accuracy degradation from the aggressive compression, the team applies a lightweight fine-tuning pass specifically designed to help the model recover some of the lost performance, followed by another round of benchmark testing.
Step six: Optimize for target hardware. Finally, the quantized model is converted into a hardware-specific format, ensuring it can take full advantage of the phone’s dedicated AI processing chip, completing the efficient LLM deployment pipeline from research model to working mobile feature.
This entire process, from twenty-eight gigabytes down to roughly three and a half gigabytes, represents an almost eightfold reduction in size, all made possible through careful, deliberate model quantization rather than building an entirely new, smaller model from scratch.
Common Myths and Misunderstandings
A few misconceptions about model quantization show up repeatedly, even among people who work adjacent to AI development.
Myth: Quantized models are just “dumbed down” versions of the original. In reality, well-executed model quantization preserves the vast majority of a model’s learned knowledge and capability. It’s compression, not simplification of the underlying intelligence.
Myth: Smaller always means significantly worse. For many everyday tasks, the difference between a full-precision model and a properly quantized version is barely noticeable to an actual user, especially at 8-bit precision.
Myth: Quantization is a one-time, simple conversion. Especially at aggressive compression levels, model quantization often involves careful calibration, testing, and sometimes additional fine-tuning to get right, rather than a single automated button press.
Myth: Only huge tech companies can do this. Thanks to open-source tools like llama.cpp and accessible libraries like BitsAndBytes, individual developers and researchers regularly apply model quantization themselves without needing massive corporate infrastructure.
Where This Technology Is Headed
The trajectory of model quantization points toward AI becoming increasingly personal, private, and instantaneous. As phone manufacturers continue building chips specifically designed to accelerate low-precision computation, and as quantization algorithms continue improving in their ability to preserve accuracy at ever more aggressive compression levels, the gap between cloud-based AI and on-device AI will likely keep shrinking.
There’s also growing interest in adaptive approaches, where a device might dynamically choose different levels of model quantization depending on the specific task, battery level, or available memory at that moment, rather than relying on a single fixed quantized version of a model. This kind of flexibility represents the next frontier of efficient LLM deployment, moving beyond static compression toward genuinely intelligent, context-aware resource management.
For everyday users in the US, UK, and everywhere else, this means the AI features quietly running on your phone are likely to keep getting faster, more private, and more capable, even as the underlying models driving them become, paradoxically, smaller and smaller.
FAQ
What is model quantization in simple terms? Model quantization is the process of reducing the precision of the numbers that make up an AI model’s internal parameters, shrinking the model’s size and speeding up its performance while trying to preserve as much of its original accuracy as possible.
Does model quantization make AI models worse? It can slightly reduce accuracy, particularly at aggressive compression levels like 4-bit, but well-executed model quantization often results in barely noticeable differences for everyday tasks like conversation, summarization, or basic writing assistance.
Why is model quantization important for efficient LLM deployment on phones? Because phones have limited memory and processing power compared to data-center servers, model quantization is essential for shrinking large models down to a size and speed that a phone can realistically handle without draining the battery or requiring an internet connection.
What’s the difference between 8-bit and 4-bit quantization? Eight-bit quantization is more conservative, offering solid memory savings with minimal accuracy loss, while 4-bit quantization is far more aggressive, offering greater memory savings but requiring more careful engineering to avoid noticeably degrading model quality.
Can I quantize a model myself without being an AI expert? Yes, tools like llama.cpp and Hugging Face’s BitsAndBytes library have made model quantization far more accessible to individual developers and hobbyists, though achieving optimal results at aggressive compression levels still benefits from experience and careful testing.
Is quantization the same as making a smaller model from scratch? No, model quantization takes an existing trained model and compresses how its numbers are stored, whereas building a smaller model from scratch involves training an entirely new, smaller network with fewer parameters from the very beginning.
Will on-device AI eventually replace cloud-based AI entirely? Unlikely to replace it completely, but efficient LLM deployment powered by model quantization is steadily expanding what’s possible on personal devices, meaning many everyday AI tasks will increasingly run locally rather than requiring a cloud connection.
Read About 10 AI Marketing Tools