Ever watched ChatGPT or Claude spit out a sentence and wondered how it actually landed on that specific word instead of a dozen other options that would’ve made just as much sense?
It’s not magic, and it’s definitely not the model “thinking” the way we do. Underneath the hood, there’s a surprisingly elegant bit of math doing the heavy lifting, and understanding it changes how you use these tools.
If you’ve ever fiddled with a setting called “temperature” in an AI playground and had no idea what it actually did besides “make things weirder,” this article is for you. We’re going to unpack the LLM temperature parameter, the softmax function that powers it, and why this tiny dial has an outsized effect on everything from customer service chatbots to AI-generated poetry.
I’ll be honest the first time I read a technical explanation of this, my eyes glazed over somewhere around the third exponential equation. So I’m going to explain it the way I wish someone had explained it to me: with analogies, real examples, and zero unnecessary jargon.
Table of Contents
- What’s Actually Happening When an AI “Picks” a Word
- The Softmax Function, Explained Without a Math Degree
- Enter the LLM Temperature Parameter
- How Softmax and Temperature Work Together
- Low Temperature vs High Temperature: Real Examples
- Why This Matters for Everyday AI Users
- Choosing the Right LLM Temperature Parameter for Your Task
- Common Misconceptions About AI “Creativity”
- A Peek Under the Hood: The Actual Math (Simplified)
- Practical Settings Cheat Sheet
- Frequently Asked Questions
- Final Thoughts
What’s Actually Happening When an AI “Picks” a Word
Large language models don’t write sentences the way we do. There’s no internal monologue, no sense of “meaning” the way you experience it when you’re drafting an email to your boss. Instead, at every single step, the model is solving one narrow problem over and over: given everything written so far, what’s the probability of each possible next word (technically, “token”) in its vocabulary?
That vocabulary might contain fifty thousand or more possible tokens. For every single one, the model produces a raw score, often called a “logit.” A higher logit means the model thinks that token is a stronger fit for what comes next. But raw logits are messy they can be negative, they can be huge, and they don’t behave like tidy probabilities that add up to 100%.
That’s where softmax comes in. And once you understand softmax, the LLM temperature parameter stops being some mysterious slider and starts making complete sense.
The Softmax Function, Explained Without a Math Degree
Picture a group of five friends voting on where to eat dinner. Each friend has a level of enthusiasm for each restaurant, but “enthusiasm” isn’t naturally a percentage. Softmax is the process that converts those raw enthusiasm levels into clean probabilities that sum to 100%, while still respecting who was more excited about what.
Here’s the intuitive version: softmax takes every score, exponentiates it (raises a constant number, roughly 2.718, to the power of that score), and then divides each result by the sum of all the exponentiated scores. The exponentiation part matters more than people realize it exaggerates differences. A word with a slightly higher score doesn’t just get a slightly higher probability; it gets disproportionately favored, because exponential functions grow fast.
This is the exact mechanism sitting at the final layer of every autoregressive language model, whether that’s GPT-4, Claude, Llama, or Gemini. The model produces logits across its entire vocabulary, softmax converts them into a probability distribution, and then the model samples from that distribution to pick the next token.
Without softmax, there’d be no coherent way to talk about “probability” of a word at all. It’s the translator between raw neural network output and something a sampling algorithm can actually use.
Now here’s the twist that most explainers skip: softmax on its own always uses the raw scores exactly as they are. If you want to control how confidently the model commits to its top choice versus how much it’s willing to gamble on less likely options, you need a second ingredient. That ingredient is the LLM temperature parameter.
Enter the LLM Temperature Parameter
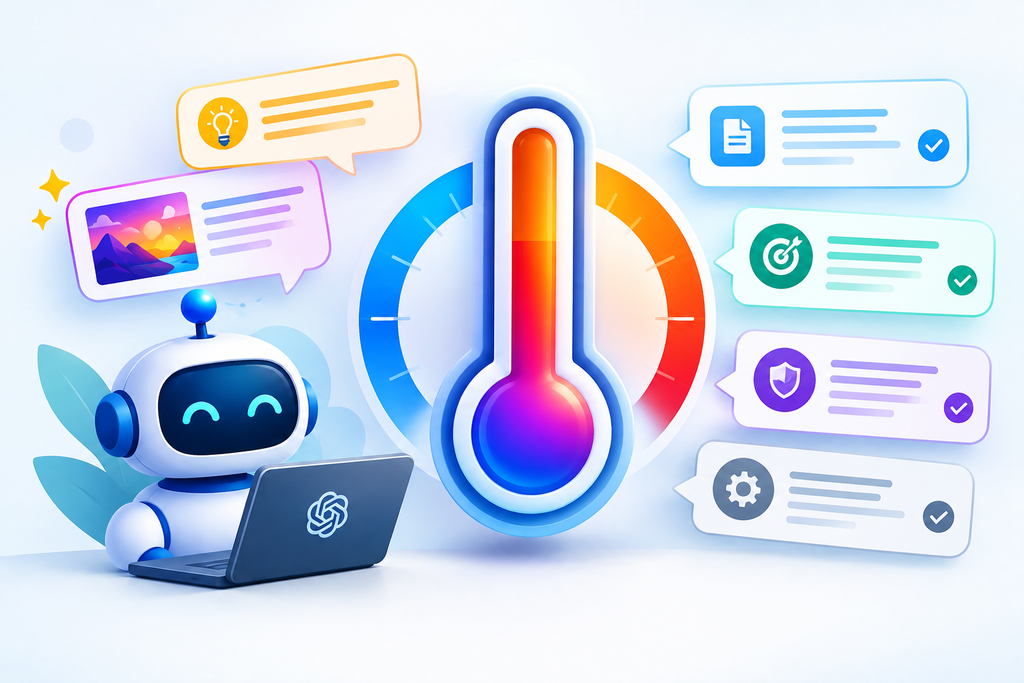
Temperature is a single number, usually somewhere between 0 and 2, that gets applied to the logits before they hit the softmax function. Mathematically, every logit gets divided by the temperature value before exponentiation happens.
That one division changes everything about how “decisive” or “adventurous” the model’s word choices feel.
When the LLM temperature parameter is low (say, 0.1 or 0.2), dividing the logits by a small number actually stretches the differences between them. The gap between the top-scoring word and the runner-up gets amplified, so soft max produces a probability distribution that’s heavily skewed toward the single best-scoring token. The model becomes predictable, safe, and consistent almost robotic in its confidence.
When the LLM temperature parameter is high (say, 1.2 or 1.5), dividing by a large number compresses the differences between logits. Words that were previously long shots suddenly become much more competitive. The probability distribution flattens out, and the model starts sampling from a wider, more diverse range of tokens. This is where you get creative, surprising, occasionally chaotic output.
Set temperature to exactly 1.0, and you’re essentially using the raw logits as-is no stretching, no compressing. That’s often called the “neutral” setting, though in practice, most production tools default somewhere between 0.7 and 0.9 because pure neutrality can still feel a bit too random for everyday use.
There’s also the edge case of temperature approaching zero. At that extreme, the model becomes almost fully deterministic, essentially always picking the single highest-probability token, a strategy known as “greedy decoding.” It’s the opposite pole from a sky-high LLM temperature parameter, which pushes the model toward near-uniform randomness across many plausible tokens.
How Softmax and Temperature Work Together
I want to slow down here because this relationship trips people up constantly. SoftMax and temperature aren’t two separate systems temperature is a modifier that feeds directly into SoftMax’s math.
Think of it like adjusting the contrast on a photo before printing it. The photo (the logits) already exists. Contrast (temperature) doesn’t add new content to the image; it just changes how sharply the existing differences show up. Crank contrast down, and everything blends into gray sameness. Crank it up, and the differences between light and dark areas become stark and dramatic.
SoftMax is the “printing” step it’s what actually turns those adjusted values into something usable (a probability distribution you can sample from). The LLM temperature parameter is the contrast dial you turn beforehand.
This is why you’ll sometimes see the process described as “temperature-scaled softmax.” It’s not a separate function; it’s the standard softmax equation with one extra division baked in. If you’ve ever seen the formula written out, it looks something like this: take each logit, divide by temperature, exponentiate the result, then normalize by the sum of all exponentiated values across the vocabulary. Simple in structure, powerful in effect.
Developers building on top of models like GPT-4, Claude, or open-source LLMs get direct access to this LLM temperature parameter through API calls. It’s usually one of the first settings you encounter, right alongside things like max tokens and top-p sampling, and for good reason — it has more visible impact on output character than almost any other setting.
Low Temperature vs High Temperature: Real Examples
Theory is nice, but let’s make this concrete. Imagine you ask a model to complete the sentence: “The weather today is…”
At a very low LLM temperature parameter (say 0.1), you’ll consistently get something like “The weather today is sunny with a high of 75 degrees.” Ask the same question five times, and you’ll likely get nearly identical completions each time. The model is playing it safe, always gravitating toward the statistically most probable continuation.
At a moderate setting (around 0.7), you start seeing variety: “The weather today is a bit gloomy, with clouds rolling in from the west,” or “The weather today is unpredictable sunshine one minute, drizzle the next.” Still coherent, still sensible, but with genuine variation between runs.
Push the LLM temperature parameter up toward 1.5 or higher, and things get interesting fast: “The weather today is whispering secrets through the maple leaves, unsure of its own mood.” Poetic? Maybe. Useful for a weather app? Absolutely not. But if you’re brainstorming creative writing, generating marketing taglines, or looking for unexpected angles, that unpredictability becomes a feature rather than a bug.
I’ve tested this directly while writing fiction with AI tools. At low temperature, dialogue between characters started sounding suspiciously similar across different scenes — same rhythms, same word choices. Bumping the LLM temperature parameter up gave each character a bit more of a distinct voice, though I also had to do more editing to fix the occasional non-sequitur.
This is the fundamental trade-off. There’s no universally “correct” LLM temperature parameter only the right setting for the specific job you’re asking the model to do.
Why This Matters for Everyday AI Users
You might be thinking: “I’m not a developer. I just use the ChatGPT app. Why should I care about any of this?”
Fair question. Here’s the honest answer: most consumer chat interfaces hide the LLM temperature parameter entirely, picking a sensible default behind the scenes. But understanding what’s happening explains a lot of behavior that otherwise seems mysterious.
Ever notice how asking the same factual question twice sometimes gives you slightly different phrasing, even when the facts are identical? That’s temperature-driven sampling variation in action, even at conservative settings. Ever notice how creative writing prompts tend to produce wilder, more varied output than technical questions? Many platforms actually adjust temperature dynamically depending on the type of task detected, or use different default settings for different product modes.
And if you do use developer tools, API playgrounds, or platforms like the Anthropic Console or OpenAI Playground, this knowledge becomes directly actionable. Knowing how the LLM temperature parameter interacts with softmax lets you deliberately steer output quality instead of randomly guessing at settings until something looks right.
Choosing the Right LLM Temperature Parameter for Your Task
Let’s get practical. Different jobs call for different settings, and after enough trial and error (plus reading what actual AI research teams recommend), some patterns become clear.
For tasks demanding accuracy and consistency code generation, data extraction, factual summarization, customer support responses a low LLM temperature parameter in the 0.0 to 0.3 range tends to work best. You want the model to reliably pick its most confident answer rather than gamble on alternatives.
For general conversation, explanatory writing, or business content, something in the 0.5 to 0.8 range typically balances coherence with enough natural variation to avoid sounding stilted or repetitive.
For creative work poetry, brainstorming, fiction, ad copy exploring unconventional angles pushing the LLM temperature parameter to 0.9 through 1.3 opens up more surprising, less predictable combinations. Just expect to do more filtering and editing, since higher temperature also increases the chance of outright nonsense or factual errors.
Beyond roughly 1.5, most practitioners find diminishing returns. Output starts to degrade into incoherence rather than useful creativity. There’s a sweet spot, and it’s rarely at the extremes.
One thing worth mentioning: temperature isn’t the only sampling control available. Parameters like top-p (nucleus sampling) and top-k work alongside the LLM temperature parameter to further shape which tokens even get considered before softmax assigns them probabilities. Top-p, for instance, restricts sampling to the smallest set of tokens whose cumulative probability exceeds a threshold, cutting off the long tail of unlikely options regardless of what temperature does. Combining these settings thoughtfully gives even finer control than adjusting temperature alone.
Common Misconceptions About AI “Creativity”
There’s a persistent myth that a high LLM temperature parameter makes a model “smarter” or “more creative” in some meaningful, intentional sense. That’s not quite right, and it’s worth clearing up.
Temperature doesn’t add knowledge. It doesn’t improve reasoning. It doesn’t give the model new ideas it didn’t already have latent probability mass toward. What it does is widen the sampling net, allowing lower-probability (but still plausible, according to the model’s training) tokens a fairer shot at being selected. Sometimes that produces genuinely delightful, unexpected phrasing. Other times it produces gibberish or factual errors, because the model wandered into territory it was less confident about.
Another misconception: people assume temperature is the only reason AI output varies between runs. In reality, sampling randomness, the specific decoding strategy (like top-p or top-k), and even subtle differences in prompt phrasing all contribute. Temperature is a major lever, but not the only one.
And a big one: some assume a LLM temperature parameter of 0 guarantees identical output every single time, across every platform. In practice, due to hardware-level floating-point nuances, parallel processing, and certain sampling implementations, you can occasionally still see minor variation even at temperature 0. It’s rare, but it happens, and it’s a good reminder that these systems, however precise the math looks on paper, run on real, imperfect hardware.
A Peek Under the Hood: The Actual Math (Simplified)
I promised no math degree required, so let’s keep this light, but seeing the actual shape of the equation helps cement the concept.
Standard softmax for a token with logit score z in a set of n tokens looks like this: probability equals e raised to the power of z, divided by the sum of e raised to the power of every logit in the set.
Temperature-scaled softmax modifies that slightly: instead of using z directly, you first divide it by temperature T. So the formula becomes: probability equals e raised to the power of (z divided by T), divided by the sum of e raised to the power of (each logit divided by T).
When T is less than 1, dividing by it makes the logits larger in magnitude, which after exponentiation dramatically increases the gap between the top choice and everything else. When T is greater than 1, dividing by it shrinks the logits, compressing the gap and flattening the resulting probability distribution.
That’s genuinely the whole trick. One division, applied before the standard softmax calculation, and the entire character of the model’s output shifts. It’s one of those rare cases in machine learning where a simple mechanism produces such a visible, intuitive effect on real-world behavior. Anyone experimenting with the LLM temperature parameter for the first time is often surprised by how much personality shift comes from such a small mathematical tweak.
Practical Settings Cheat Sheet
Here’s a quick-reference breakdown based on common use cases, useful if you’re working directly with an API or an advanced settings panel:
Coding and technical documentation: keep the LLM temperature parameter around 0.0 to 0.2 for reliability and reduced hallucination risk.
Customer support and factual Q&A: aim for roughly 0.2 to 0.4, prioritizing consistency over variety.
General writing assistance, emails, summaries: 0.5 to 0.7 tends to feel natural without becoming repetitive.
Brainstorming, ideation, marketing copy: 0.7 to 1.0 introduces welcome variety while staying mostly coherent.
Creative fiction, poetry, experimental content: 1.0 to 1.3, accepting that some outputs will need editing or discarding.
Pure novelty or chaos generation, rarely useful in production: 1.4 and above.
These aren’t hard rules — they’re starting points based on how most practitioners and documentation from major AI labs frame the trade-offs. Testing on your specific use case always beats blindly following a chart, but having a baseline saves a lot of trial and error.
Frequently Asked Questions
What is the LLM temperature parameter in simple terms?
It’s a setting that controls how predictable or random an AI model’s word choices are. Low values make output more focused and repeatable; high values make it more varied and surprising.
What does the softmax function actually do in AI models?
Softmax converts a model’s raw output scores (logits) into a clean probability distribution across all possible next words, ensuring the probabilities add up to 100% while preserving the relative confidence between options.
Is a higher LLM temperature parameter always better for creative writing?
Not necessarily. While higher temperature increases variety and unexpected phrasing, going too high often produces incoherent or nonsensical text. Most creative applications work best somewhere between 0.8 and 1.3.
Does the LLM temperature parameter affect factual accuracy?
Indirectly, yes. Lower temperature settings favor the model’s most confident answer, which tends to align better with well-established facts. Higher temperature increases the chance of the model selecting less likely, potentially less accurate tokens.
Can I set the LLM temperature parameter to zero?
Yes, and doing so pushes the model toward nearly deterministic output, almost always selecting the single highest-probability token at each step. Some minor variation can still occur due to hardware-level factors, but output will be highly consistent.
Does every AI model use softmax and temperature the same way?
The core mechanism is nearly universal across autoregressive language models, but exact default temperature values, available ranges, and additional sampling controls (like top-p or top-k) can differ between platforms and providers.
Why do ChatGPT and Claude sometimes give different answers to the same question?
Sampling randomness combined with the LLM temperature parameter setting means the model isn’t always picking the exact same token at every step, even when the underlying probability distribution is similar.
Read about The Powerful Math Behind Machine Learning: Why Linear Algebra Runs the Show