I once pasted an entire ninety-page contract into a chatbot and asked it to find every clause related to termination fees. A couple of years ago, that request would have gotten me a polite apology and a truncated response, because the model simply couldn’t hold that much text in its head at once.
This time, it read the whole thing, cross-referenced clauses from page four with page seventy-one, and gave me a clean summary in seconds. Nothing about the model’s core intelligence had fundamentally changed overnight. What changed was its LLM context windows.
If you’ve ever wondered why some AI chatbots seem to “forget” what you said ten messages ago while others can hold an entire novel’s worth of information in mind, the answer almost always comes back to this one architectural detail. In this article, we’re going to open up the hood and really understand how an LLM context windows works, why attention mechanism memory is the engine behind it, and what it actually means for how you use these tools day to day.
Table of Contents
- What a Context Window Actually Is
- Why This Concept Matters More Than People Realize
- The Building Block: Tokens, Not Words
- Attention Mechanism Memory Explained Simply
- Why Bigger Context Windows Are Hard to Build
- The Evolution of Context Window Sizes Over Time
- Techniques Engineers Use to Extend Memory
- The “Lost in the Middle” Problem
- Real-World Examples From Major AI Models
- A Mini Case Study: Reading a Long Document
- Common Myths About Context Windows
- Practical Tips for Working Within a Context Window
- Where This Technology Is Headed
- FAQ
- Final Thoughts
What a Context Window Actually Is
Let’s start with the basics, because this term gets thrown around constantly without much explanation.
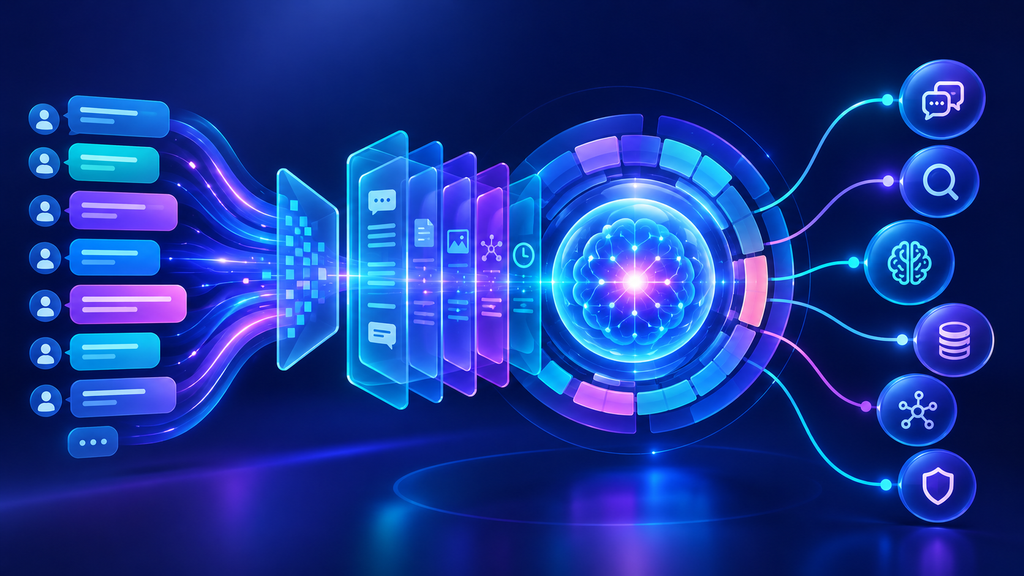
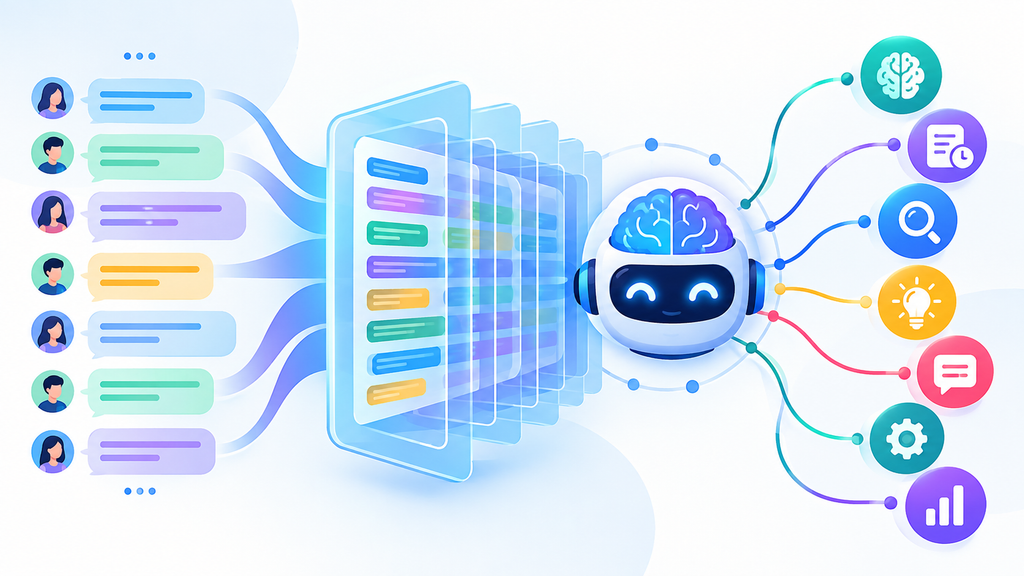
An LLM context windows is essentially the amount of text a language model can actively “see” and consider at any given moment during a conversation or task. Think of it like short-term memory, except instead of a vague, fuzzy sense of what was said earlier, it’s an exact, mathematically precise record of every word, sentence, and instruction within a defined boundary.
Everything you’ve typed in a conversation, along with everything the model has responded with, gets fed back in as part of that window every single time you send a new message. The model isn’t remembering your conversation the way a person does, pulling from some internal diary. It’s re-reading the entire visible conversation from scratch each time, up to the limit of its LLM context windows, and generating a response based on everything currently inside that boundary.
Once a conversation grows longer than that boundary allows, older parts of the conversation start getting pushed out, the same way an overflowing inbox eventually starts archiving your oldest emails to make room for new ones.
Why This Concept Matters More Than People Realize
It’s easy to treat context window size as just another spec sheet number, similar to comparing megapixels on a camera. But the size of an LLM context windows genuinely changes what’s possible to do with an AI system.
A small context window limits a model to short exchanges, quick questions, and simple tasks. Ask it to help debug a small function, and it works fine. Ask it to review an entire codebase, and it simply can’t, because most of that codebase would never fit inside its field of view in the first place.
A larger LLM context windows unlocks an entirely different category of use case. Legal teams can drop in entire contracts. Researchers can feed in dozens of academic papers at once. Novelists can have an AI reference their entire three-hundred-page manuscript for consistency checks. None of that is possible without enough working memory to actually hold all that information simultaneously.
This is also why context window size has become one of the most closely watched, competitively advertised features among AI companies. It’s not just a technical curiosity. It directly determines the ceiling of what the tool can practically do for you.
The Building Block: Tokens, Not Words
Before going further, it helps to clarify something that trips a lot of people up. When engineers talk about the size of an , they’re not measuring it in words. They’re measuring it in tokens.
A token is a chunk of text, which might be a whole word, part of a word, or even just punctuation, depending on how the model’s internal vocabulary breaks things down. As a rough rule of thumb, a hundred words in English translates to roughly seventy-five to a hundred and thirty tokens, depending on sentence complexity and vocabulary.
This distinction matters because it explains why a context window advertised as “one hundred thousand tokens” doesn’t translate to one hundred thousand words of usable space. It’s closer to seventy-five thousand words, and that number shrinks further once you account for the model’s own response also needing to fit somewhere within that same total budget. Every LLM context windows has to account for both what goes in and what comes out.
Attention Mechanism Memory Explained Simply
Now for the part that actually makes all of this possible under the hood: attention mechanism memory.
Modern language models are built on an architecture called the transformer, and the defining feature of a transformer is something called self-attention. Here’s the plain-language version of what that means.
When a model processes a piece of text, it doesn’t just read left to right in a strict sequence and forget everything as it goes, the way older AI architectures did. Instead, for every single word or token it’s currently processing, the model looks back across every other token currently sitting inside its LLM context windows and calculates how relevant each of those other tokens is to the one it’s focused on right now.
Imagine reading a mystery novel where, every time a new clue appears, you instantly and simultaneously re-evaluate how it connects to every previous clue in the book, weighing which earlier details matter most for understanding this new piece of information. That’s roughly what attention mechanism memory does, except it happens mathematically, across every token, almost instantaneously.
This is genuinely different from just storing text in a database and retrieving it later. Attention mechanism memory creates dynamic, weighted relationships between every piece of information inside the LLM context windows, which is exactly why a well-designed model can connect a detail mentioned at the very beginning of a long document to a question asked about the very end of it.
The catch, and this is the crucial engineering challenge, is that calculating these relationships between every single token and every other token becomes dramatically more computationally expensive as the amount of text grows. This is the central tension that shapes nearly every decision engineers make about LLM context windows design.
Why Bigger Context Windows Are Hard to Build
If attention mechanism memory is so powerful, why didn’t companies just build massive context windows from the very beginning?
The honest answer comes down to math, and specifically, a problem often referred to as quadratic scaling. In a standard transformer architecture, the computational cost of attention mechanism memory grows roughly with the square of the number of tokens involved. Double the size of your LLM context windows, and you don’t just double the computing cost, you roughly quadruple it.
This creates real, practical limits. A context window twice as large doesn’t just need twice the memory and processing power, it needs dramatically more, which translates directly into higher costs, slower response times, and greater strain on the hardware running the model.
For years, this quadratic relationship was treated almost like an unavoidable law of nature within AI research. Getting past it required genuinely creative engineering, and a lot of the progress we’ve seen in expanding the LLM context windows of modern models comes directly from finding clever ways to work around this scaling problem rather than simply throwing more raw computing power at it.
The Evolution of Context Window Sizes Over Time
It’s worth appreciating just how quickly this has moved, because the pace of change here has been genuinely remarkable.
Early conversational AI systems commonly worked with context windows in the range of two thousand to four thousand tokens, roughly the length of a few pages of text. That was enough for a short conversation, but nowhere near enough to analyze a full document or maintain a long, detailed back-and-forth.
Within just a few years, mainstream models pushed their LLM context windows capacity into the tens of thousands of tokens, then past one hundred thousand, and now some leading models offer context windows exceeding one million tokens, enough to hold an amount of text comparable to several long novels stacked together.
This progression wasn’t just a matter of engineers deciding to raise a number. Each meaningful jump required real breakthroughs in how attention mechanism memory gets calculated, stored, and managed efficiently, since naive scaling using the original transformer approach would have made million-token context windows computationally impossible with any reasonable hardware budget.
Techniques Engineers Use to Extend Memory
So how did engineers actually get around the quadratic scaling problem to expand the LLM context window so dramatically? A few key techniques deserve mention.
Sparse Attention
Rather than calculating full attention mechanism memory relationships between every single token and every other token, sparse attention techniques selectively focus computation on the most relevant relationships, skipping calculations that are unlikely to matter much. This significantly reduces computational cost while trying to preserve most of the useful connective reasoning that makes attention so powerful.
Sliding Window Attention
This approach has each token pay attention primarily to a limited, nearby range of surrounding tokens rather than the entire document at once, similar to reading with a moving spotlight rather than trying to hold the whole page in view simultaneously. It’s efficient, though it can weaken a model’s ability to connect very distant pieces of information within a large LLM context windows.
Positional Encoding Improvements (RoPE and ALiBi)
Transformers need some way of understanding word order and relative position within text. Techniques like Rotary Positional Embeddings, commonly called RoPE, and Attention with Linear Biases, known as ALiBi, improved how models track position information in ways that generalize much better to longer sequences than earlier positional encoding methods, directly supporting larger LLM context window capacity without a proportional loss in coherence.
Memory Compression and Caching
Some architectures use techniques that compress or summarize earlier parts of a conversation into a more compact internal representation, rather than keeping every single token in full detail forever. This allows a system to effectively extend its usable attention mechanism memory without linearly increasing raw computational cost for every additional token.
Retrieval-Augmented Approaches
Rather than trying to fit everything directly into the model’s native LLM context windows, some systems instead retrieve only the most relevant chunks of a much larger document or knowledge base and feed just those relevant pieces into the model. This is a practical workaround that extends effective memory without requiring the underlying model itself to natively support an enormous context window.
The “Lost in the Middle” Problem
Here’s something that surprises a lot of people, and it’s an important nuance often left out of marketing materials focused purely on context window size.
Research has repeatedly shown that models don’t always use their full LLM context windows with equal attention. Information placed near the very beginning or very end of a long input tends to get weighted more heavily and recalled more accurately than information buried in the middle. This phenomenon has been informally nicknamed the “lost in the middle” problem.
Think about it like studying for an exam by reading a long textbook chapter start to finish. You’ll probably remember the opening concepts clearly, and the closing summary vividly, but that dense paragraph on page fourteen might blur together with everything else in the middle. Language models can experience a mathematically similar pattern, even with a technically enormous LLM context windows available to them.
This matters practically. If you’re feeding a model a long document and asking a question about something buried deep in the middle, you might get a noticeably less accurate answer than if that same information appeared near the start or end. Understanding this limitation helps explain why simply having access to a massive context window doesn’t automatically guarantee perfect recall of everything inside it.
Real-World Examples From Major AI Models
This isn’t just theoretical. The size and quality of an LLM context windows directly shapes how different AI products actually behave for everyday users in the US and UK.
Some modern assistants offer context windows large enough to process entire books in a single pass, enabling use cases like analyzing a complete research paper collection, reviewing an entire legal case file, or summarizing months of chat history without losing earlier details.
Coding assistants increasingly rely on expanded context windows to understand entire codebases at once, rather than just the single file a developer happens to have open, allowing for far more accurate suggestions that account for how different parts of a project actually interact with each other.
Customer support systems use extended attention mechanism memory to maintain awareness of a customer’s entire interaction history across a long support session, rather than losing track of earlier details the customer already explained, which used to be a common and frustrating experience with older, more limited chatbot systems.
A Mini Case Study: Reading a Long Document
Let’s make this concrete with a realistic walkthrough of how an LLM context windows actually gets used in practice.
Imagine a small business owner uploads a ninety-page vendor contract and asks an AI assistant to identify every clause related to early termination penalties.
Step one: The entire document gets converted into tokens, likely somewhere between thirty and forty thousand tokens for a document that length, well within the capacity of a modern large LLM context windows.
Step two: As the model processes the request, attention mechanism memory calculates relationships between the user’s specific question about termination penalties and every relevant chunk of text throughout the document, regardless of where that text physically appears.
Step three: Recognizing the “lost in the middle” risk, a well-designed system might also apply techniques like re-reading key sections or structuring its internal reasoning to double-check middle sections more deliberately, rather than relying purely on default attention weighting.
Step four: The model synthesizes references from multiple sections, potentially connecting a clause on page twelve with a related definition on page sixty-eight, something that would be genuinely difficult and time-consuming for a human to catch manually without careful, dedicated review.
Step five: The final summary gets generated, drawing on the full available LLM context windows rather than being limited to just the first few pages, which is precisely the kind of task that simply wasn’t possible with the smaller context windows available just a few years earlier.
Common Myths About Context Windows
A handful of misunderstandings show up again and again in conversations about this topic.
Myth: A bigger context window always means a smarter model. Context window size affects how much information a model can consider, not necessarily how well it reasons about that information. A model with a huge LLM context windows but weaker underlying reasoning can still underperform a smaller, more capable model on complex tasks.
Myth: Models remember conversations the way people do. In reality, most systems simply re-process the entire visible conversation each time, up to the boundary of their LLM context window, rather than storing memories in any humanlike sense.
Myth: You should always fill the entire available context window. Cramming excessive, irrelevant information into a LLM context windows can actually dilute a model’s focus and, due to the lost in the middle effect, may reduce accuracy on the specific question you actually care about.
Myth: Context window size is the only thing that matters for long conversations. Attention mechanism memory quality, positional encoding techniques, and how well a system handles the middle sections of long inputs all matter just as much as the raw numerical size advertised.
Practical Tips for Working Within a Context Window
Understanding how an LLM context window actually works can genuinely change how you use these tools more effectively.
Place critical information strategically. Given the “lost in the middle” tendency, if you’re including a long document alongside a specific question, consider restating your most important question or instruction again near the end of your message, not just at the very beginning.
Break extremely long tasks into focused chunks. Rather than dumping an enormous amount of unrelated information into a single LLM context windows, consider breaking complex projects into more focused, sequential conversations when practical.
Don’t assume perfect recall automatically. Even with a generous context window, it’s worth occasionally double-checking that a model correctly referenced earlier details, especially for high-stakes tasks like legal or financial document review.
Be mindful of cost and speed trade-offs. A larger LLM context window generally means slower responses and higher computational cost, so matching your context usage to what a task actually requires, rather than maximizing it unnecessarily, tends to produce better practical results.
Where This Technology Is Headed
Research into expanding and improving the LLM context windows shows no signs of slowing down. Engineers continue developing more efficient attention mechanism memory techniques aimed at pushing past the quadratic scaling problem even further, potentially enabling context windows that can meaningfully process entire extensive knowledge bases in a single pass.
There’s also growing interest in hybrid approaches that combine massive native context windows with intelligent retrieval systems, giving models the best of both worlds: genuine, direct attention-based reasoning over recently relevant information, combined with the ability to selectively pull in additional context from much larger external sources when needed.
Solving the “lost in the middle” problem more thoroughly is another active area of focus, since raw context window size alone doesn’t guarantee that a model actually makes full, even use of everything technically available to it.
For everyday users in the US, UK, and beyond, this steady progress means the AI tools you interact with will likely keep getting better at handling genuinely long, complex, multi-part tasks, remembering earlier details in a conversation more reliably, and connecting dots across large amounts of information without losing the thread partway through.
FAQ
What exactly is an LLM context window? An LLM context window is the maximum amount of text, measured in tokens, that a language model can actively consider at one time, including both the conversation history and its own generated response.
Why do some chatbots seem to forget earlier parts of a conversation? Once a conversation exceeds the size of a model’s LLM context windows, older parts of the exchange get dropped to make room for newer messages, which can create the impression that the model has forgotten earlier details.
What is attention mechanism memory in simple terms? Attention mechanism memory is the process by which a language model calculates how relevant every piece of text within its context window is to every other piece, allowing it to connect related information regardless of where it appears.
Does a bigger context window always mean better answers? Not necessarily. While a larger LLM context windows allows a model to consider more information, factors like reasoning quality and the “lost in the middle” effect also significantly influence how accurately that information actually gets used.
What does “lost in the middle” mean? It refers to a documented tendency for language models to recall information placed near the beginning or end of a long input more reliably than information buried in the middle of a large LLM context windows.
How is context window size measured? It’s measured in tokens rather than words, with a token typically representing a word, part of a word, or a punctuation mark, meaning the usable word count is somewhat lower than the advertised token number.
Can I do anything to get better results from a long context window? Yes, placing your most important instructions or questions near the beginning and end of your input, rather than burying them in the middle, tends to produce more reliable results given how attention mechanism memory typically prioritizes information.